Photo by Lilian Do Khac on Unsplash.
Last Saturday evening I typed this into Oh My Pi: “Is there a way to hand omp or Hermes a plan and have it run in a loop: plan in fable, execute in sonnet, repeat”. I had a 69-task hardening checklist for Ankusa, my Elixir webhook receiver, with Done when and Proof lines on every task.
I’m on a Claude Max plan, whose weekly limit resets at a fixed time each week. A loop turns what’s left on Saturday into merged PRs while I’m away.
I landed on two markdown files under ~/.omp/agent/: a /plan-loop command and a plan-worker agent, the prewalk split from my setup post run unattended.
Two markdown files
The orchestrator is a slash command
~/.omp/agent/commands/plan-loop.md is a file slash command, so the orchestrator is a prompt. I run /plan-loop ANKUSA_HARDENING_PLAN.md and it keeps the books:
- It never edits files, and its git use stops at
fetch,showandrev-parse. - It reads the plan from
origin/main, where merged ticks show what is done. (after: 2, 5)tags name prerequisites by bullet number and sort bullets intodone,in-flight,blocked,waitingandready.- It
waits instead of polling, ends with one table, and never retries a blocked bullet.
The dispatch rule, verbatim:
Keep at most 3 bullets in flight. Whenever fewer than 3 are in flight and some bullet is `ready`, dispatch the lowest-numbered ready bullets with the task tool, one item each, `agent: "plan-worker"`:
The worker is a custom agent
~/.omp/agent/agents/plan-worker.md is a custom task agent:
---
name: plan-worker
description: Owns one bullet of a committed checklist plan end to end in its own git worktree — plans it read-only, implements it, opens a PR, waits for green CI, squash-merges. Dispatched by /plan-loop.
model: anthropic/claude-fable-5-1
thinking: high
prewalk: "@executor"
---
model is the planner, Fable 5.1 at high. Prewalk switches the session to the executor role (anthropic/claude-sonnet-5-5 in my config.yml) at the first edit, which is always the worker ticking its own checkbox, so the planner writes no implementation code.
Each worker:
- Works in
<repo>.plan-loop/b<n>on branchplan/<plan stem>-b<n>, resuming any commits already there. - Plans read-only into a todo list that starts with the tick and ends with “PR, CI, merge”.
- Runs the repo’s checks as
lockf -k -t 14400 LOCK <command>, so three workers never run docker-compose or a full build at once. - Opens a ready PR and fixes up to three red CI rounds from
gh pr checks --watch --fail-fast. - Squash-merges, cleans up, and ends with one line:
RESULT: merged <url> <sha>orRESULT: blocked <reason>; PR <url|none>.
A blocked result is final, so the reason has to say what I need to decide.
Making it your own
/plan-loop <plan.md>takes any committed markdown with checkboxes. Write the acceptance into each task, because the worker merges on its own.modelRoles.executorswaps the implementer, for example toanthropic/claude-fable-5-1:max;task.agentModelOverridesswaps the planner per agent.(after: N)is the only ordering the loop reads. MyDeps:lines were prose, so Ankusa PR #167 tagged 13 open bullets before today’s rerun.RESULT:is the whole contract. Change what done means in the worker’s step 5 and the orchestrator doesn’t care.omp -pruns it headless. The command warns: “Underomp -p, ending the turn exits omp and kills every running worker.”
Before Ankusa I ran it on a scratch repo: bullets 1 to 6 merged, and bullet 7 blocked on a leftover worktree’s uncommitted yo.sh, which the worker refuses to discard.
Watching it run
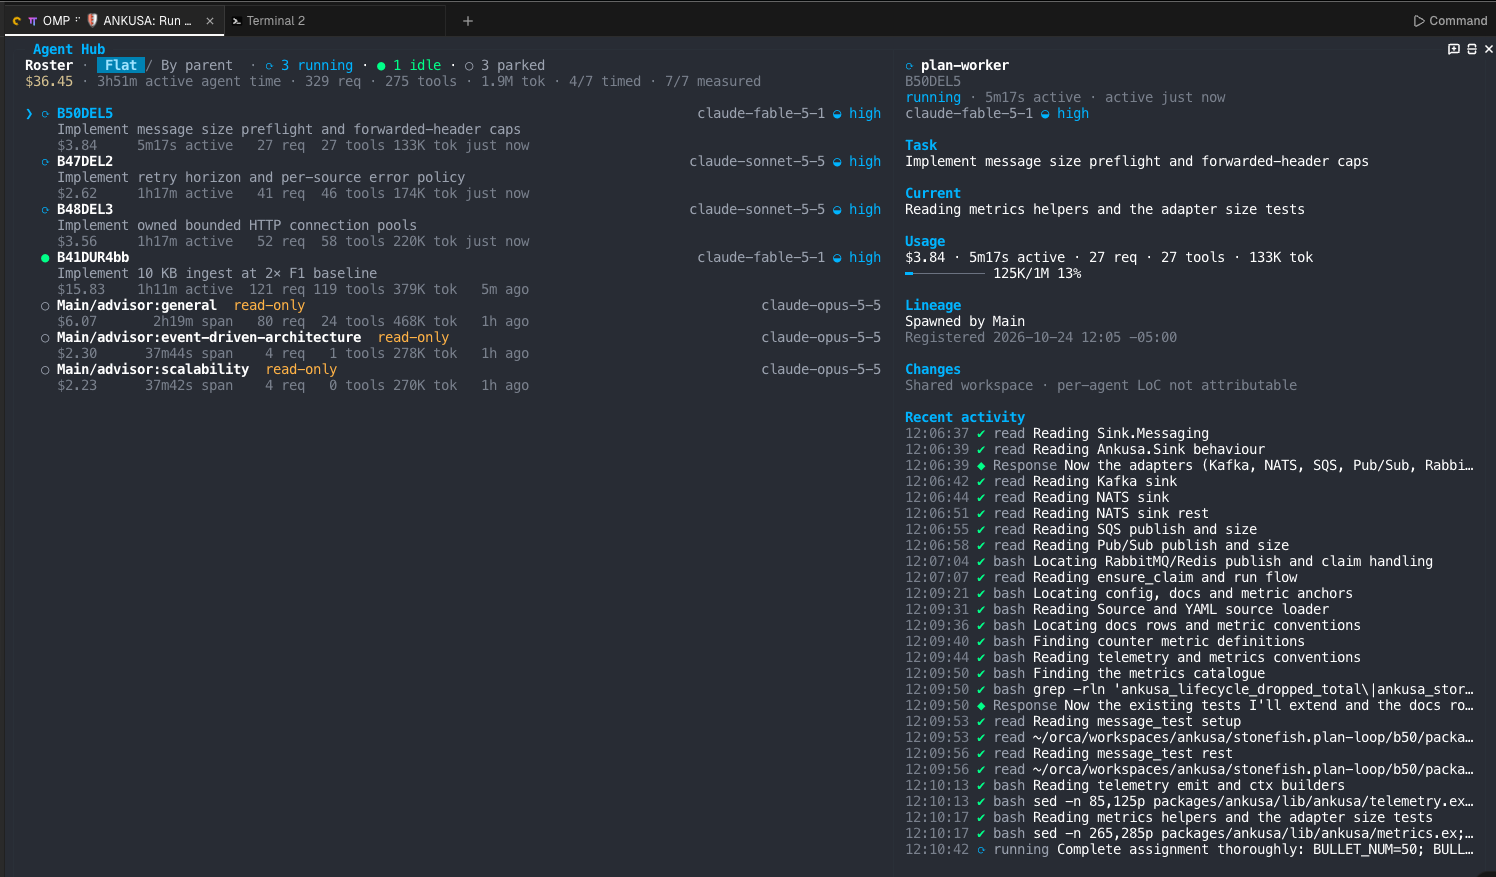
This is OMP’s Agent Hub (Alt+A) during today’s rerun. Workers are named by bullet and task id:
B47DEL2andB48DEL3showclaude-sonnet-5-5, so they’re past the handoff and implementing.B50DEL5is five minutes in onclaude-fable-5-1, still planning. The inspector shows it reading the Kafka, NATS, SQS and Pub/Sub sinks.B41DUR4bbis idle. It came back blocked after 1 hour 11 minutes:
RESULT: blocked DUR-4.b.b's ≥ 2× at 10 KB cannot be reached by product code: the bench harness itself ... bounds the cell at ~1.6× F1 ... the acceptance or the bench needs a user decision; PR none
That’s what I want: it measured, found the acceptance out of reach, and stopped instead of fudging the benchmark.
The three parked rows are my WATCHDOG.yml advisors, built as in my advisors post: General, Event-Driven Architecture and Scalability, on Opus 5.5, watching the orchestrator. General reviews every turn (80 requests). The specialists use reviewMode: agent-end and the orchestrator rarely ends a turn, so 4 each. Over the weekend, 35 of the specialists’ 43 notes were about worker code the orchestrator can only forward. One, after I asked “I see we return seq again… why?”, found seq still in every GET /v1/dlq row at admin/router.ex:1063.
End of the week
Both runs dispatched their first workers on a Saturday, spending what was left of the week’s allowance before the reset. The first started October 17 at 21:51, and by 05:33 Tuesday it had merged 46 PRs. That morning I sent “Let’s wind it down after the current tasks wrap up. I’m done for the day.”
I sent 16 nudges, such as “are some of the agents stuck??” and “launch an agent to periodically improve the build process too so these complete faster!”. That one spawned side agents that landed 12 CI and tooling PRs; #122 cut the check run from 1174 s to 923 s.
Today’s rerun lost its morning to a plug_crypto CVE that turned every Elixir job red until #168 fixed it, then dispatched bullets 41, 47 and 48, and 50 once 41 blocked.
Was the Ankusa run any good?
Good, with two loop bugs the run exposed.
What went right:
- 45 of 69 tasks merged in 54 hours: 46 PRs, +82,083/−6,506 lines, median 52 minutes from open to merge, no human review, and no reverts on
mainsince. - 45 of 46 PR bodies carry a
Verified locally:section. #141, the largest at +4,965 lines, lists “mise run check:packageforankusa(1419 passed, 48 properties, 88.72 % coverage) …mise run test:crash(acked=15092 recovered=15092 missing=0)”. - Blocked results told the truth. TEN-5’s worker reported “6/7 tests green … but no package checks, docs, PR or merge”. The orchestrator broke its no-retry rule for both budget blocks and two workers lost to a provider refusal, and all four merged on the next try (#126, #142, #103, #104).
What went wrong:
mainwas red after 16 of the 46 merges, with seven failed runs in a row from #145 to #151 until #153 fixed a Kafka test teardown.- #150 merged 3 minutes 49 seconds after opening: its checks were slow to appear, so the worker’s fallback (“the repo has no PR CI, so continue to merge”) fired.
perf gate, both crash drills andankusa_kafkathen failed on it. That’s step 5.3 of the worker file, not bad luck. - Three repair PRs fixed loop output (#123, #130, #153), all tests and tooling.
- The nightly soak F1 added has failed all six runs since October 19, most recently with
FAIL: missing 630399: accepted hooks that no sink delivered. Nightly E2E is red too, though F5’s fleet job passes.
The good parts come from Done when lines the worker could not skip. Both bugs are rules in plan-worker.md: merge when no checks show up, and never look at main after the merge.
How it adds up
Two markdown files and a checklist turned a week’s leftover allowance into 45 merged hardening tasks. Twenty-four tasks are left, and three workers were on them as I wrote this.


